
Automated document processing is software that reads business documents, pulls out the data, checks it against your rules, and writes it into your systems with people only reviewing the exceptions. The biggest savings come from a few high-volume, high-error workflows, not from automating every file. Miniml builds these pipelines through its document intelligence services, starting with the paperwork that costs the most.
Most teams do not have a document problem. They have a handful of workflows that quietly eat headcount, delay cash and create audit risk.
Key Takeaways on Automated Document Processing
- Invoices, insurance claims, contracts, KYC files and purchase orders usually carry the highest cost per document because they combine volume, variation and rework.
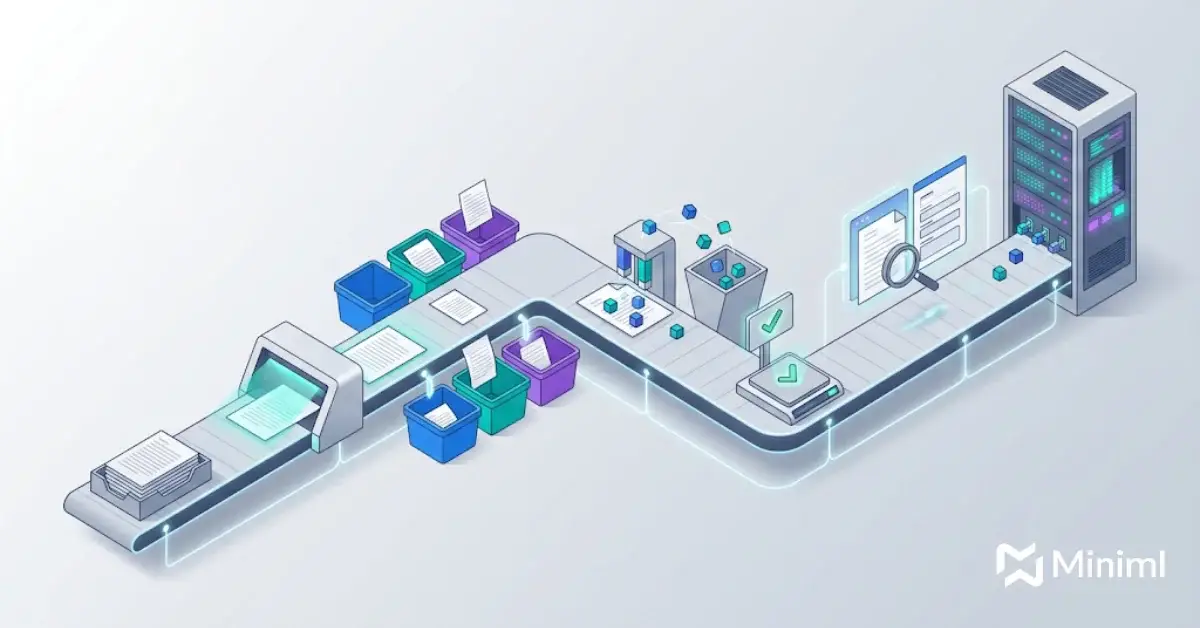
- An automated document processing pipeline has seven stages: capture, OCR, classification, extraction, validation, human review and system write-back.
- Cost per document should include exception handling and rework, not just keying time.
- LLM-based document intelligence handles layout variation that breaks template OCR, but it still needs validation rules and a review queue.
- Payback from automated document processing is easiest to prove on one workflow with a clear baseline, then expand.
Which Document Workflows Cost the Most?
The cost of paperwork is not spread evenly. It piles up where documents arrive in large numbers, look different every time, and feed a decision with money attached.
Here are the five workflows that usually cost enterprise teams the most, and where automated document processing pays off first:
- Supplier invoices. High volume, many layouts, and every error turns into a duplicate payment, a late fee or a vendor dispute.
- Insurance and warranty claims. Long, mixed packets with forms, photos, receipts and letters, where each claim needs several fields checked against a policy.
- Contracts and amendments. Low volume but high value. Missed renewal dates, pricing clauses or liability caps cost far more than the time spent reading.
- KYC and onboarding files. Identity documents, proof of address and company records that must be checked, logged and retained for regulators.
- Purchase orders and delivery notes. Simple on paper, but matching them to invoices and receipts is where most exceptions start.
Two companies with the same invoice volume can have very different cost per invoice and cycle times. Most of that gap comes from how much manual handling, chasing and rework each document needs.
For finance teams, these workflows are often the first stop for AI in finance because the baseline cost is easy to measure and the data already lives in an ERP.
How Does Automated Document Processing Work?
Document processing automation is not one model reading a PDF. It is a pipeline, and a system that skips validation or review will break on the first batch of real scans.
- Capture. Documents arrive from email inboxes, upload portals, scanners, EDI feeds and shared drives. The capture layer pulls them into one queue with metadata such as sender, date and source.
- OCR and layout reading. The system turns images and scanned PDFs into text while keeping the layout: tables, key-value pairs, checkboxes and reading order.
- Classification. Each page or packet is sorted by type. A claim packet might contain a claim form, three receipts and a police report, and each needs different handling.
- Extraction. The system pulls the fields that matter, such as invoice number, totals, line items, dates, parties, policy numbers or clause text, into a structured record.
- Validation. Extracted values are checked against business rules and reference data: line items must add up to the total, the PO must exist, the supplier must be approved and the ID must match the application.
- Human review. Anything that fails validation or comes back with low confidence goes to a reviewer, who sees the document and the extracted fields side by side and corrects them.
- System write-back. Approved records are written into the ERP, claims platform, CRM or contract repository, with an audit trail that links each value back to the source page.
Confidence scores drive the split between straight-through processing and review. Most automated document processing platforms return a confidence value for each extracted field, and you set the threshold that decides whether a value is accepted automatically or flagged for a person. For any automated document processing system that touches payments or compliance, a human review stage for low-confidence fields is the right default.
For contracts, teams also want to ask questions across thousands of documents, which is where knowledge retrieval systems sit on top of the same pipeline.
Manual vs Template OCR vs LLM-Based Document Intelligence
Not every automated document processing workflow needs the newest approach. The right choice depends on how much your documents vary and how costly an error is.
| Factor | Manual processing | Template-based OCR | LLM-based document intelligence |
|---|---|---|---|
| How it reads documents | People key data by hand | Fixed zones or rules per layout | Models read layout and context |
| New supplier or form layout | No setup, but slow | New template needed each time | Usually handled without a new template |
| Tables and line items | Accurate but slow | Breaks on multi-page or shifting tables | Handles most variation, still needs checks |
| Unstructured text (clauses, letters) | Possible, slow | Poor | Strong at finding and summarizing |
| Setup effort | Hiring and training | High per template | Moderate, focused on rules and evaluation |
| Best fit | Very low volume or rare edge cases | Stable, standard forms | Varied, high-volume, mixed packets |
Many automated document processing setups in production mix all three: template OCR for stable forms, LLM-based extraction for varied invoices and claims, and people for the exceptions.
How Do You Calculate Cost Per Document?
Most business cases only time the data entry. The real cost per document includes everything between arrival and a clean record in your system:
- Handling time. Minutes to open, read, key and file one document, multiplied by the loaded hourly cost of the person doing it.
- Exception time. The share of documents that need follow-up, multiplied by the extra minutes each one takes.
- Error cost. Duplicate payments, missed discounts, late fees, claim leakage or compliance findings traced back to bad data.
- Delay cost. Slower cycle times that hold up cash, approvals or customer onboarding.
- Overhead. Supervisors, quality checks, storage and the tools people use today.
Add these up and divide by monthly volume to get your current cost per document. Then estimate the same figure after automation: platform and model costs per page, plus reviewer time on the documents that still go to the review queue.
A Worked Payback Formula
For automated document processing, payback in months equals the one-time build cost divided by the monthly saving. The monthly saving is your old cost per document minus your new cost per document, multiplied by monthly volume.
The number that moves payback most is the straight-through rate: the share of documents that pass validation with no human touch. Measure it weekly from day one. Our earlier guide to AI document processing and extraction covers accuracy measurement in more depth.
Where Document Automation Projects Go Wrong
Document automation fails in predictable ways, and most are operating problems, not model problems.
- Starting with the hardest document instead of a high-volume workflow with a clear baseline.
- No labeled test set, so nobody can tell whether accuracy is improving or slipping.
- Skipping write-back, so someone still keys extracted data into the ERP.
- No owner after launch to watch drift as formats and models change.
Integration is often the longest part of an automated document processing project. Our guide to common AI implementation challenges covers the patterns that hold up in production.
For background on the field, see this overview of document processing methods. Most pipelines still start with optical character recognition.
Automated Document Processing FAQs
What is the difference between document automation and automated document processing?
Document automation often refers to generating documents, such as filling contract templates or producing letters from data. Automated document processing runs the other direction: it reads incoming documents and turns them into structured data. Many teams need both, for example reading a signed contract and then generating the renewal notice from the extracted dates.
Is document intelligence the same as OCR?
No. OCR turns images into text. Document intelligence goes further: it understands layout, classifies document types, extracts specific fields, and checks them against rules. OCR is one stage inside a document intelligence pipeline, and on its own it still leaves people to find and key the values that matter.
How long does it take to see payback?
Payback from automated document processing depends on volume, current cost per document and how many documents pass straight through. High-volume invoice or claims workflows with a clear baseline tend to show results fastest. Measure the baseline before you build, then track straight-through rate and reviewer time weekly.
Can automated document processing handle handwriting and poor scans?
Modern OCR and vision models read many handwritten fields and low-quality scans, but accuracy drops as quality falls. Route low-confidence fields to human review rather than accept them blindly. Better capture at the source often helps more than a new model.
Do we need to send documents to a public AI service?
Not necessarily. Automated document processing for sensitive files such as KYC records, medical claims or legal contracts can run on private cloud deployments or on open-weight models hosted in your own environment. Decide the setup based on your data rules and regulators before picking a vendor.
Which workflow should we automate first?
Pick the workflow with high volume, a measurable cost per document, and a clear system to write results into. For most companies that is supplier invoices or a single claim type. Prove the straight-through rate and payback there, then reuse the same automated document processing pipeline for the next document type.
Start With the Document That Costs You Most
The fastest route to value with automated document processing is one workflow, one baseline and one production pipeline that writes clean data into the system your team already uses. Miniml’s AI Workflow Opportunity Map (3 weeks) ranks your document workflows by cost and readiness, and our Production-Readiness Review (2 weeks) checks an existing pilot before it goes live.
Miniml
San Francisco: 50 California St #1500, San Francisco, CA 94111, United States. Phone: +1 415-941-8345
Edinburgh: 93 George St, Edinburgh EH2 3ES, United Kingdom
Book a consultation with Miniml to find out which of your documents are worth automating first.
About Miniml: Miniml is an AI consultancy with offices in San Francisco and Edinburgh that helps enterprise teams take AI systems past the pilot and into production.